The Operational Question
When a data center cooling zone warms up, the first visible symptom may be a high supply-air temperature, a rising return-water temperature, or a CRAH unit that appears to be calling for more cooling without getting it. The operational question is narrower: is the chilled-water control valve actually moving the amount of water the system needs, and can the team prove that the command, position feedback, and physical flow all agree? This post gives facilities managers and technicians a practical way to investigate that question before a localized cooling issue becomes a thermal event, an avoidable service call, or an unstable operating condition.
The goal is not to teach a technician to force a valve open or bypass a control sequence. It is to establish a safe, repeatable troubleshooting conversation between the operator at the BMS, the technician at the CRAH or air handler, and the mechanical team responsible for the chilled-water plant. By the end, readers will have a pre-task checklist for separating a control problem from a mechanical restriction, documenting what they observed, and choosing training that matches the people doing the work.
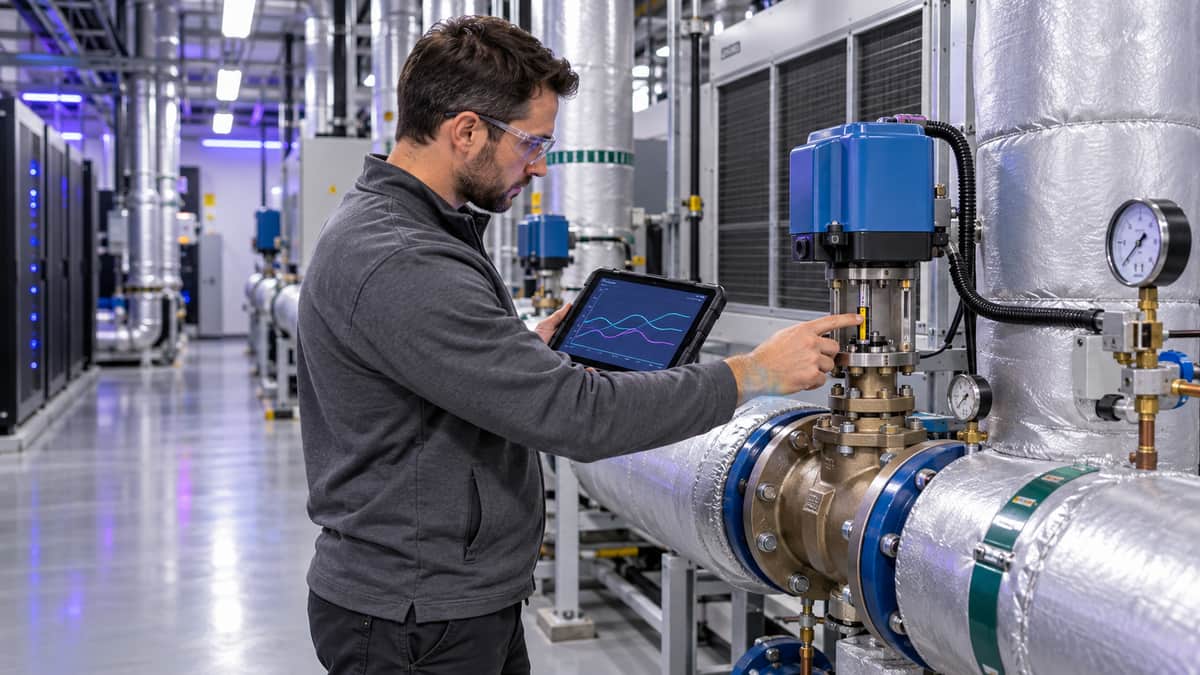
In a typical chilled-water data center, a valve command is only one piece of the cooling chain. The BMS may request a position based on supply-air temperature, discharge-air temperature, or a sequence tied to load. The actuator should respond. The valve stem or shaft should move. Differential pressure and water temperature should support the expected coil performance. A sensor, network point, or linkage problem can make any one of those statements appear true when it is not.
Who This Affects
This issue can appear in almost any site with water-cooled air-handling equipment or a chilled-water distribution system:
- Enterprise data centers with central chilled-water plants and multiple air-handler zones.
- Colocation facilities where landlord plant controls and tenant-area equipment meet at a handoff boundary.
- Hyperscale or campus sites with long piping runs, many valve assemblies, and staged cooling sequences.
- Edge facilities that use packaged or compact chilled-water equipment with limited on-site mechanical staffing.
- Commissioning and maintenance contractors returning a CRAH unit or air handler to service after a component change.
The people most likely to encounter the problem are facility managers, controls technicians, HVAC and mechanical technicians, data center operators, and commissioning agents. NOC staff may be the first to notice a trend, while an operations manager decides whether the affected load can remain online during troubleshooting. EHS leaders and permit coordinators become involved when the work requires isolation, electrical access, refrigerant-adjacent work, confined-space evaluation, or access to a restricted mechanical area.
The situation is especially common after a maintenance window, a controls upgrade, a seasonal changeover, a filter or coil service, a chilled-water plant change, or a new hall turnover. It can also show up when a valve has not moved through its normal range for a long time. A good troubleshooting plan therefore includes both the immediate alarm and the recent work history.
What Can Go Wrong
A valve position problem can create a mismatch between what the control system believes and what the cooling coil receives. If the BMS displays an 80 percent command but the actuator is stalled at 20 percent, the operator may continue to raise the command while the room temperature climbs. If the feedback point is frozen at an old value, the team may misdiagnose a mechanical fault as a controls fault. If the valve is open but the coil has inadequate differential pressure, more command will not create more useful flow.
The consequences are operational as well as mechanical:
- A single row or zone can develop a hot spot even while average room temperature looks acceptable.
- Affected CRAH units may run fans harder, increasing electrical use and masking the missing cooling capacity.
- Operators may make repeated setpoint changes that cause hunting, overshoot, or unstable control behavior.
- An unplanned intervention can disturb adjacent equipment or remove a needed redundancy path.
- A contractor may replace an actuator or sensor without resolving a closed isolation valve, strainer issue, air problem, or differential-pressure limitation.
- In a colocation environment, poor documentation can turn one tenant alarm into a dispute about responsibility and response time.
Safety boundaries matter. A valve investigation may seem like a low-energy task, but actuators have electrical components, pumps and fans can start automatically, and water systems can be hot, pressurized, or chemically treated. If a technician must remove guards, open a panel, isolate equipment, or place a hand near moving parts, the site procedure should define the required authorization and control of hazardous energy. OSHA's lockout/tagout requirements are a useful regulatory reference for covered servicing and maintenance activities, but a web article does not replace the employer's energy-control procedure or the site's permit process.
The same caution applies to sensor readings. A trend that looks impossible should be treated as a clue, not an invitation to defeat an alarm. Before changing a control parameter, the team should know which sequence is active, who owns the setpoint, what rollback looks like, and how the change will be recorded.
What Managers Should Check
Managers should make sure the troubleshooting plan starts with evidence and a clear stop point. The following checklist helps keep the investigation focused.
- Define the affected boundary. Identify the room, row, CRAH, air handler, coil, valve tag, and BMS points involved. Record when the symptom began and whether it follows load, time of day, or a recent work order.
- Confirm the operating condition. Capture supply-air temperature, return-air temperature, chilled-water supply and return temperatures, valve command, valve feedback, fan status, and any active alarms. Use the same timestamp for each reading where possible.
- Check the active sequence. Determine whether the unit is in normal cooling, economizer, lead-lag, low-load, manual, override, or fail-safe mode. A valve command that seems wrong may be correct for a different sequence.
- Compare command with feedback. Look for a reasonable response when the control signal changes within the approved test method. A fixed feedback value, a large command-to-feedback difference, or a delayed response should be documented before anyone adjusts the linkage.
- Verify the actuator and linkage visually. With the equipment in a safe state and within the site's permitted observation boundary, check for loose couplers, damaged brackets, unusual noise, missing insulation, signs of water leakage, and travel indicators that do not match the displayed position.
- Check isolation and flow path status. Verify that the correct isolation valves are open, strainers and filters are addressed by the maintenance plan, and the affected circuit is not unintentionally bypassed. Do not remove a strainer cover or break a connection without an approved isolation and draining plan.
- Review differential pressure and temperatures. Compare the affected circuit with a healthy peer unit under a similar load. A valve can be fully open while the coil still underperforms because available differential pressure, water temperature, or heat-transfer surface is not adequate.
- Inspect the control point history. Look for oscillation, slow travel, abrupt step changes, manual overrides, stale communication, or a recent change to limits and deadbands. Save a trend or screenshot according to the site's evidence policy.
- Coordinate the test window. Tell the control-room operator, affected tenants or customers when applicable, electrical and mechanical teams, and the incident owner what will be changed and what conditions require a stop. Protect redundant cooling before taking equipment out of service.
- Close with a proof test. After repair or adjustment, verify command, movement, feedback, temperatures, alarms, and trend stability. Record the normal value and the acceptance criteria so the next technician does not start from an undocumented assumption.
Managers should also check whether the site has the right spares and references. An actuator model, valve authority, wiring diagram, controls point list, and manufacturer service instruction can save hours. The maintenance record should identify whether the issue was caused by a component failure, a configuration change, a physical restriction, a sensor error, or an operating sequence that needs engineering review.
A simple decision framework
If command and feedback disagree, start with the point, actuator, linkage, and wiring path. If they agree but temperatures and flow do not, move the investigation toward differential pressure, isolation status, strainers, coil condition, air in the circuit, or plant-side capacity. If the mechanical evidence looks normal but the zone still drifts, review the sequence, sensor placement, airflow, and the relationship between the cooling zone and the actual IT load.
That framework is deliberately conservative. It keeps the team from treating every temperature alarm as a valve problem and from treating every valve command as proof of cooling capacity. It also creates a clean handoff between controls and mechanical specialists.
Which Training Fits This Situation
The best training path depends on who owns each step. A controls technician who reads BMS trends may need different preparation from a mechanic who checks actuators, strainers, coil condition, and pump-side behavior. A facility manager needs enough system context to ask good questions and protect the work window without pretending to perform specialized service.
For a technician who diagnoses the cooling chain, HVAC Systems Troubleshooting Essentials is a practical starting point. It supports a methodical approach to symptoms, measurements, and equipment interactions. Mechanical Systems & Equipment Maintenance is relevant when the work involves maintenance planning, physical condition, component replacement, and returning equipment to service.
For a manager or engineer responsible for system behavior, Cooling Systems Design & Optimization helps connect individual valve behavior to coil performance, distribution, plant capacity, and efficiency decisions. It is useful when repeated valve complaints point to a broader design or operating issue rather than a single failed actuator.
The Cooling & Facilities Efficiency Bundle is the better fit when a team needs both design context and maintenance depth. Its role-based path includes cooling design, HVAC troubleshooting, energy efficiency and PUE, mechanical maintenance, cooling and refrigerant safety, and building-envelope fundamentals. That breadth can help a site avoid a common gap in which operators understand the alarm screen but not the mechanical reason behind the alarm.
Training should sit inside a role-based plan. A new operator might first learn the cooling sequence, alarm priorities, and escalation process. A mechanical technician may add equipment maintenance and safety modules before participating in hands-on work. A facilities manager may combine system optimization with operations management and incident-response training. These are knowledge and best-practice courses. They support a training program and provide a certificate of completion after finishing, but they do not replace site qualification, supervised hands-on practice, an employer's energy-control program, or any license or regulatory requirement.
Before assigning a course, managers should ask:
- Will this person read trends, operate controls, perform mechanical service, or approve the work?
- Which equipment is actually installed at this site: CRAH units, air handlers, chillers, pumps, or a combination?
- Does the site need one narrow module for an immediate gap or a bundle for a new maintenance team?
- How will knowledge be reinforced through procedures, walkdowns, shadowing, and post-work review?
That approach makes training a reliability control rather than a catalog purchase. The right course should improve the team's ability to recognize the symptom, choose a safe next step, and document the result.
Common Mistakes to Avoid
- Treating a BMS command as proof that water is flowing through the coil.
- Replacing an actuator before checking isolation valves, linkage, feedback, wiring, and the active sequence.
- Changing setpoints or deadbands during a live thermal problem without recording the original values and rollback plan.
- Testing a valve in manual override and forgetting to return the unit to its approved automatic sequence.
- Comparing an affected unit with a peer that has a different load, coil arrangement, or plant operating condition.
- Ignoring low differential pressure, trapped air, fouled strainers, or a partially closed valve elsewhere in the circuit.
- Sending a contractor into a mechanical or electrical area without confirming access, escort, permit, and communication requirements.
- Closing the work order with “valve adjusted” instead of recording the cause, measurements, final position behavior, and proof-test result.
- Assuming a course completion certificate is a substitute for hands-on qualification or site-specific authorization.
One more mistake is letting the problem remain isolated in the controls team's queue. A valve-position symptom often crosses controls, mechanical, operations, and capacity planning boundaries. The work order should identify the owner for each question and the person who decides whether the equipment can remain in service.
Key Takeaway
A chilled-water valve investigation is most useful when it compares four things: the cooling demand, the control command, the physical movement, and the resulting flow and temperature behavior. That comparison helps a data center team avoid blind setpoint changes, unnecessary parts swaps, and unsafe troubleshooting around energized or pressurized equipment. It also turns one alarm into a reusable maintenance lesson.
This week, choose one CRAH or air-handler valve assembly, walk through the checklist with the operator and mechanical technician, and record the normal command-to-feedback response in the site's maintenance documentation.